Missions M-02
FitNova Call Intelligence
Scores every sales call on five coachable dimensions, and refuses to report any flag it can't quote verbatim from the transcript.
Objective
FitNova sells programs through advisors who take calls all day. Per call, a manager needs to know: did the advisor find the customer’s goals, handle objections without overpromising, and stay compliant? Constraint: the calls are heavily Hinglish, and full of Aadhaar numbers, PANs and phone numbers.
Baseline
A team lead samples a handful of calls a week. Most calls are never reviewed, and which ones are becomes politics.
System
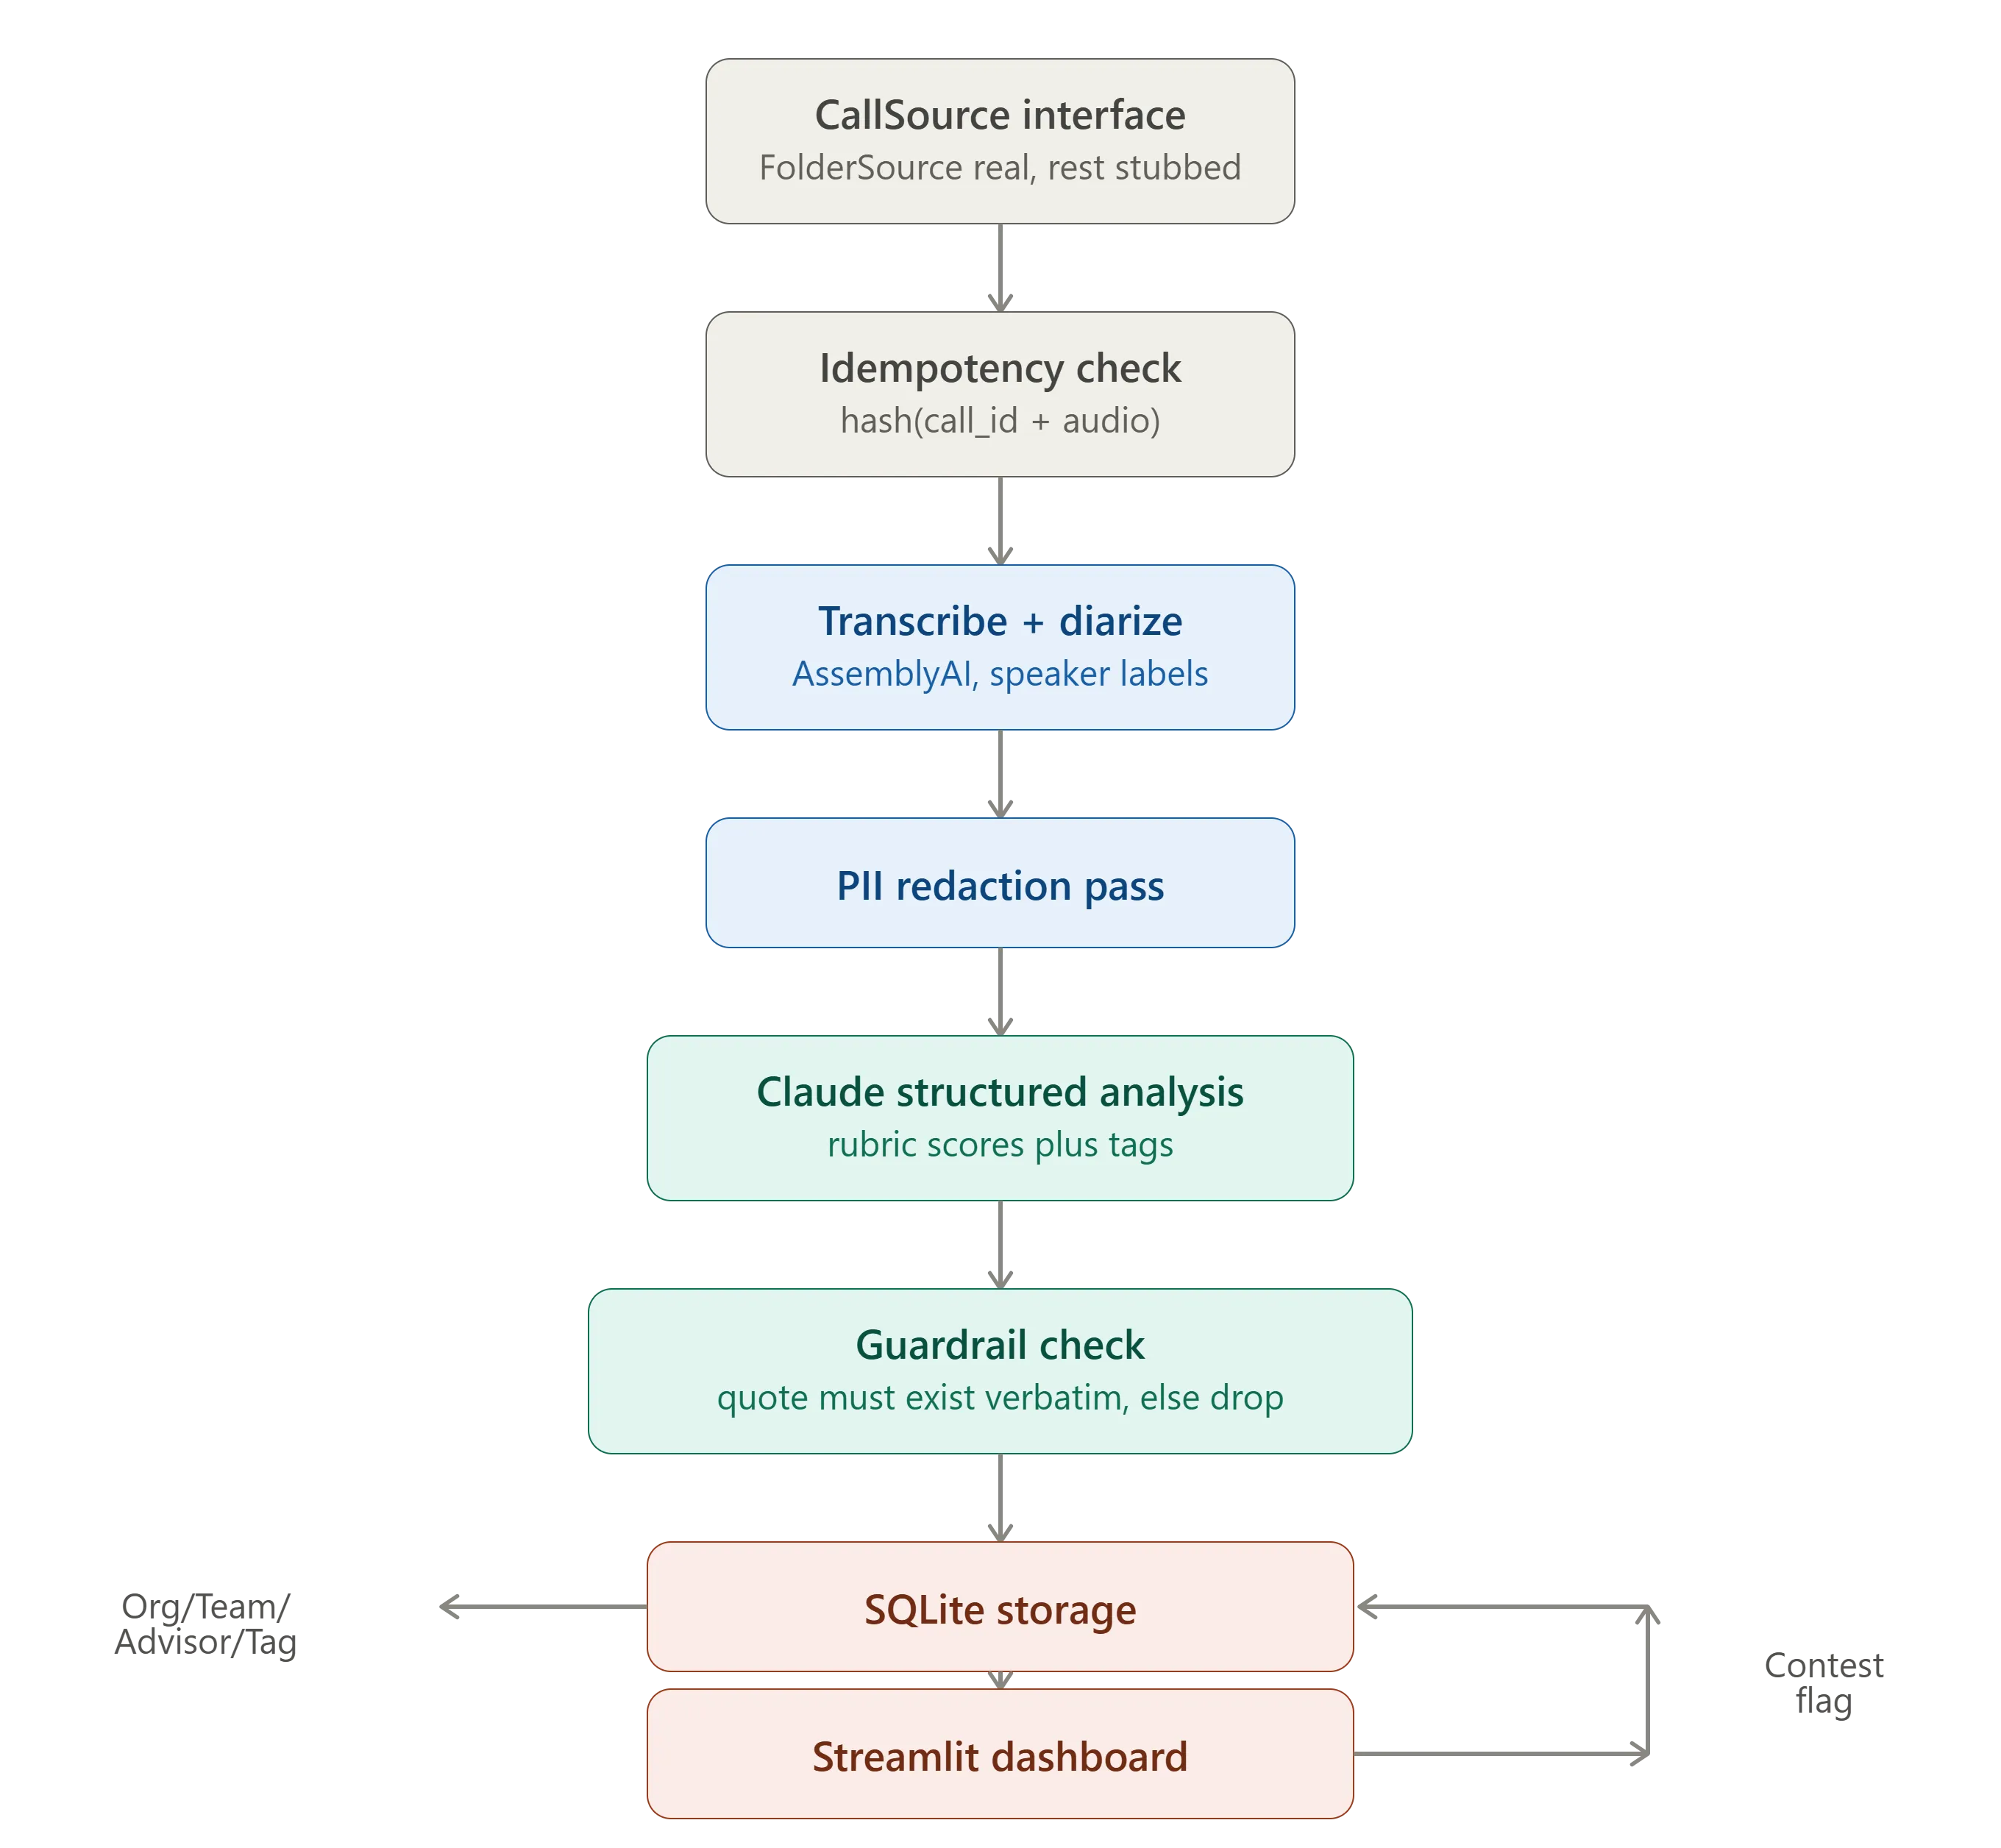
Four stages, plus a human loop on top:
- Ingestion behind a
CallSourceabstract class. Telephony or CRM adapters are one file each; the pipeline never changes. - Transcription + diarisation with AssemblyAI, language auto-detect for Hinglish. Speakers mapped advisor/customer by a first-speaker heuristic (calls are outbound).
- Two-layer PII redaction. AssemblyAI’s server-side redaction, then a local pass with spaCy NER plus regex for Indian identifiers (Aadhaar, PAN, PIN codes), on the transcript and on the model’s output. Each layer has different blind spots; a leak in either is a leak.
- Analysis with Claude tool-use: a closed set of 7 issue tags with severities, and 5 scores (needs discovery, product knowledge, objection handling, compliance, next-step booking).
Audio is SHA-256 hashed under a unique constraint, so retries can never double-count a call. 12 FastAPI endpoints with role-scoped auth: directors see the org, team leads their team, advisors their own calls.
Eval
What exists today is a hard contract instead of a metric: no tag ships unless its quote is in the transcript, in both the LLM path and the rule-based fallback.
Anomalies
A-1 · Plausible quotes that were never said. Ask a model for “the line where the advisor overpromised” and it returns a line in exactly that shape, whether or not anyone said it. Fix:
for tag in response.tags:
    if tag.quoted_line not in transcript:
        log.dropped(tag, reason="quote_not_verbatim")
        continue
That turns every claim into a fact a human can check in seconds: the property a compliance tool actually needs.
A-2 · Diarisation fails silently on bad audio. On mono or low-quality audio, every segment is now tagged unknown and the call is flagged diarization_quality="failed". It degrades loudly instead of scoring garbage confidently.
A-3 · Known limits, documented in the README:
- SQLite + an in-process queue collapse past ~50 calls/hour, and queued tasks are lost on restart → Celery + Postgres.
- Inbound calls break the first-speaker heuristic → voice-print or the CRM caller field.
- Hindi-dominant segments can slip past English-tuned prompts → bilingual few-shot prompts.
- The TTL cache is unbounded → capped LRU or Redis.
Outcome
The pipeline runs end to end and the dashboard is live (demo credentials in the repo README). Advisors can contest a flag and a team lead upholds or dismisses it, and every disagreement between model and human is stored, so systematic model errors show up in the data.
The pattern I reuse everywhere now: if an LLM claim can’t be checked against its source by a dumb, deterministic test, it’s a rumour, not a feature.