Missions M-03
Sentinel-AI
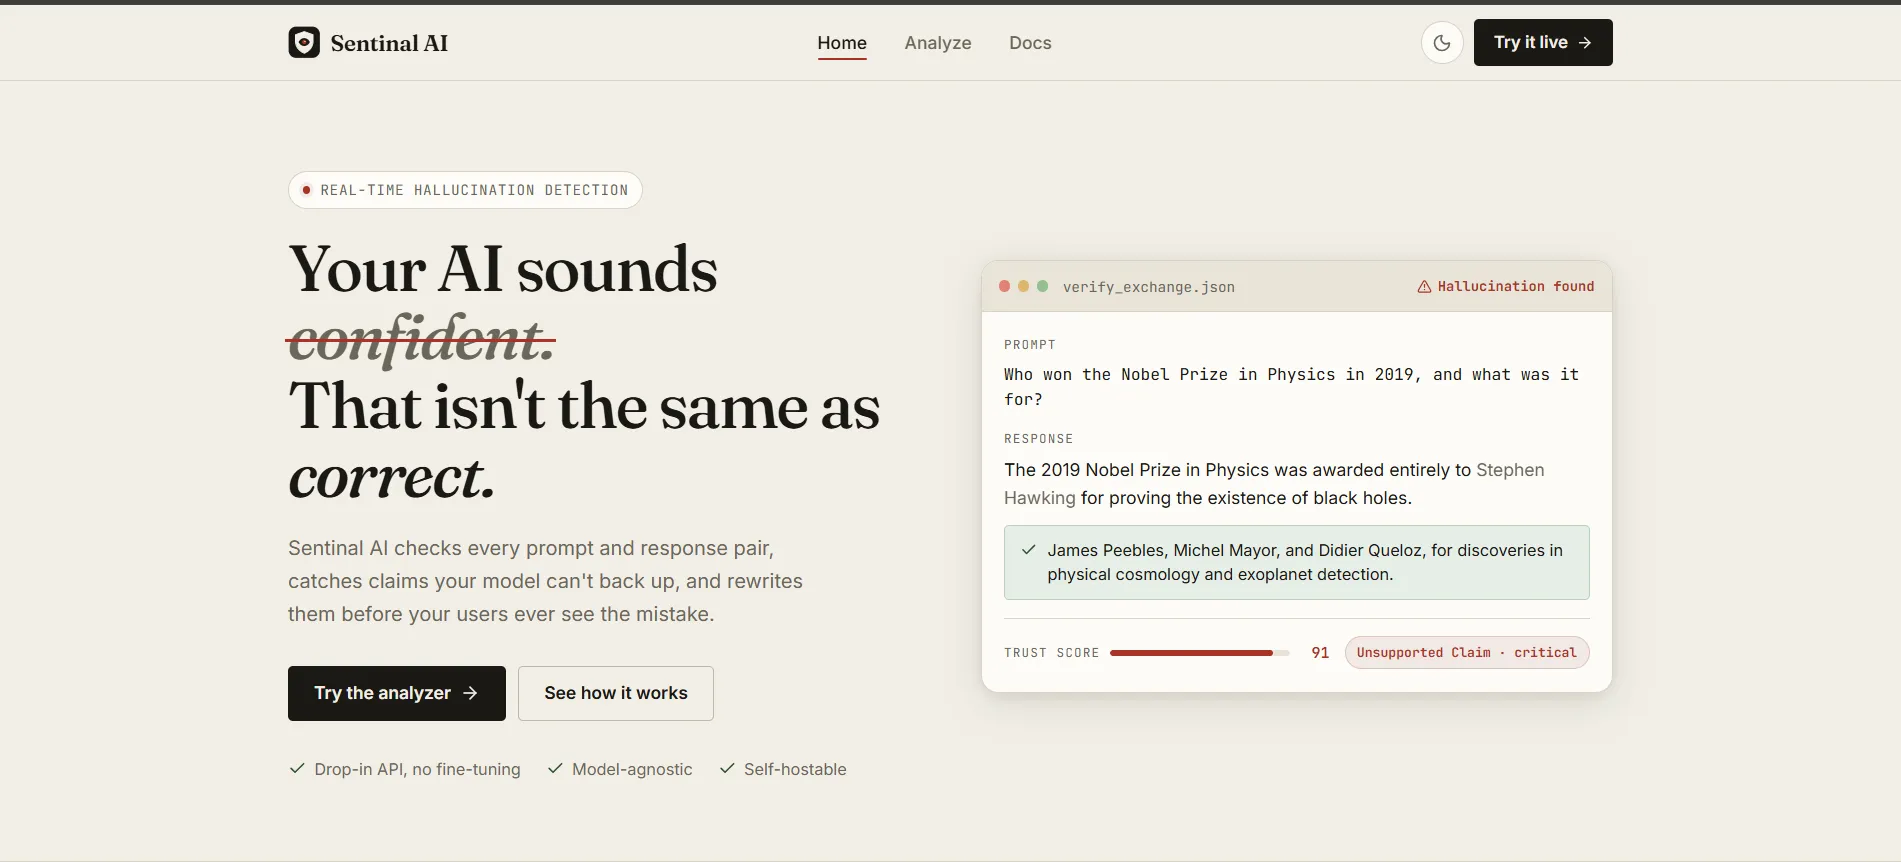
Sits beside your LLM and scores every prompt/response pair 0 to 100, with the claims and flags that produced the score, and a policy that decides serve, fix or block.
Objective
Production LLM apps need to know, per response, whether to serve it, fix it or stop it (and why), without putting another model in the generation path.
Baseline
Ship the model’s output as-is, or wrap it in a generic moderation endpoint that returns a label with no reasons.
System
Model-agnostic: Sentinel observes prompt/response pairs and never sits in the generation path. Three detectors per request:
| Detector | Side | Checks |
|---|---|---|
| Prompt anomaly | Prompt | Distribution shift vs. baseline prompts |
| Jailbreak RAG | Prompt | Embedding similarity to known jailbreak patterns |
| Output risk | Response | 8 categories: violence, hate, self-harm, illegal activity, misinformation, privacy, inappropriate, harmful instructions |
The SDK’s verify() adds local factual-claim checking: it extracts numeric claims from the response, cross-checks each against the prompt context, marks it consistent, unverified or contradicted, and auto-corrects contradictions when the prompt holds the right value.
result = client.verify(prompt="Our refund policy is 60 days.",
                       response="We offer 30-day refunds.")
result["status"]     # "hallucinated"
result["corrected"]  # "We offer 60-day refunds."
Scores map to policy: 0 to 24 serve · 25 to 59 auto-correct or review · 60 to 100 block and escalate. Blocking, monitoring, async-with-webhooks and self-hosted modes.
Eval
Anomalies
Outcome
Live at sentinelaihq.com, SDK on PyPI as sentinelai-risk, docs on GitHub Pages.